Introduction: Myths and Reality Behind Its Demise
The boom of AI chatbots like ChatGPT and Google Gemini sparked predictions that blogs would die. However, reality shows otherwise. Demand for high-quality content with structured depth has actually increased, as generative language models require reliable and organized data sources. Consequently, the primary goal of blog content shifts from earning clicks toward becoming a primary reference for generative search technologies.
Self-Sufficient Information Architecture: Definition and Importance
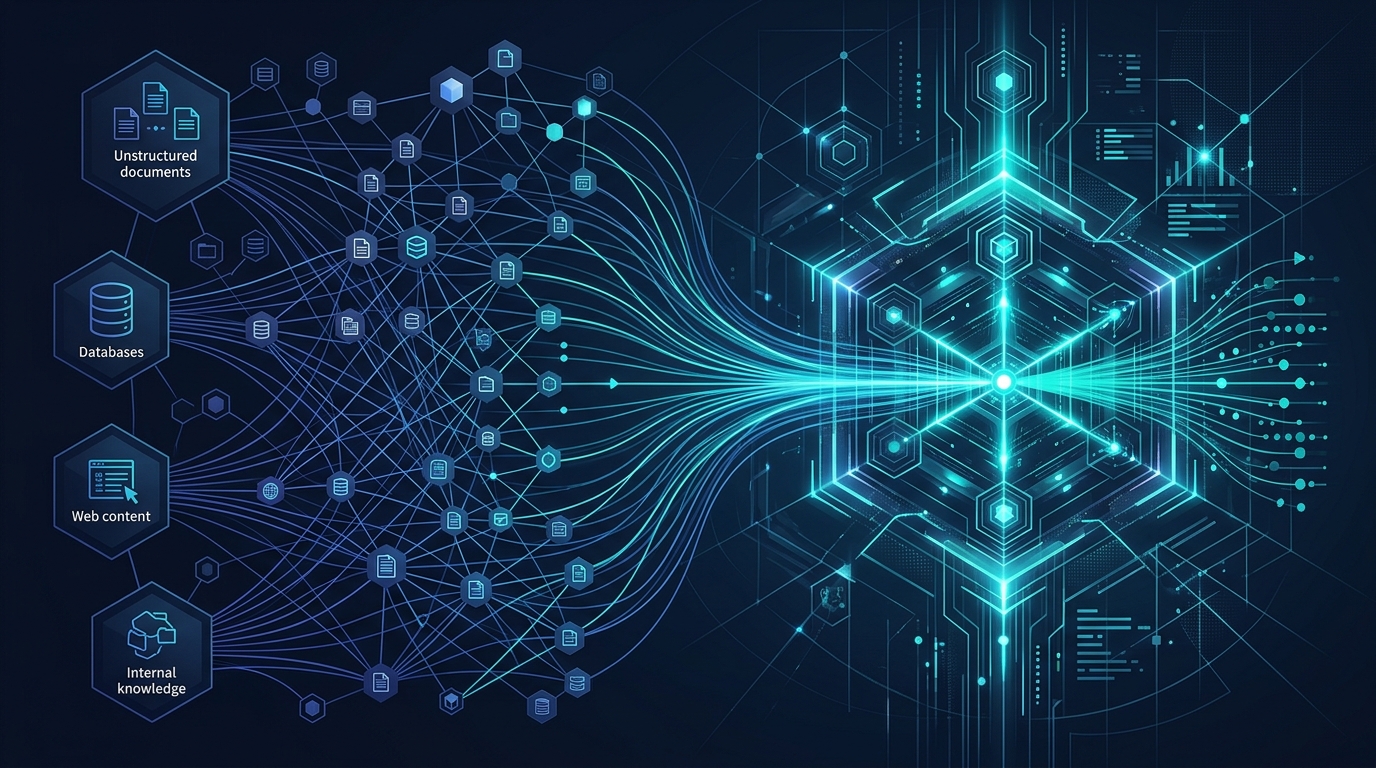
Self-sufficient information architecture is the foundation that differentiates a blog from mere publishing platforms. It encompasses hierarchical structures, semantic metadata (such as schema.org), and intuitive navigation that enables language models to retrieve and understand content accurately. Without this architecture, blogs risk being swallowed by unstructured information overload. To assess readiness, content producers must ask: Is our blog infrastructure prepared to become a primary data source for AI?
New Performance Indicators: Measuring Contribution in the AI Ecosystem
Traditional metrics like bounce rate and CPC clicks become irrelevant. Instead, we need to measure retrieval rates (voice share in AI results), engagement time on long snippets, and conversions from users who utilize blog information to complete tasks. Visibility is no longer the main objective, but rather positioning within the 'knowledge map' used by generative models. Internal data analysis, not just standard Google Analytics, becomes crucial for optimizing blog contributions.
Case Studies: Successful and Failed Adaptations
Many enterprise blogs have successfully increased retrieval by generative models after redesigning their information architectures. They focus on consistent and measurable structures. Conversely, failed cases usually rely solely on old SEO optimization or ignore data structure. The common success factor is investment in consistent and measurable information frameworks, proving that architectural adaptation is essential.
Practical Steps: Building Infrastructure for Retrieval
To build infrastructure ready for retrieval, conduct technical checklists: audit URL structures, implement metadata schemas, and simplify navigation for efficient crawling. This transformation is not a single IT project, but cross-functional collaboration (editorial, engineering, data). Use automation tools to monitor performance as a data source for generative search, ensuring our content remains relevant and accessible.
Conclusion: Summary and Call to Action
In conclusion, blogs that survive in the generative search era are those answering the question: 'How does my blog become a useful knowledge database for machines?' This adaptation requires long-term commitment and a data-driven iteration culture. Begin by identifying core entities in your niche, then design their information architecture. Thus, blogs remain relevant and provide added value amidst AI technological advancements.
Pengantar: Mitos dan Realitas di Balik Kematiannya
Boom chatbot AI seperti ChatGPT dan Google Gemini sempat memicu ramalan bahwa blog akan mati. Namun, realitanya justru sebaliknya. Permintaan akan konten berkualitas dengan struktur dan kedalaman informasi malah meningkat, karena model bahasa generatif membutuhkan sumber data yang andal dan terstruktur. Oleh karena itu, tujuan utama konten blog bergeser dari mendapatkan klik menuju menjadi referensi primer bagi teknologi pencarian generatif.
Arsitektur Informasi Mandiri: Definisi dan Pentingannya
Arsitektur informasi mandiri adalah fondasi yang membedakan blog dari sekadar platform publishing. Ini mencakup struktur hierarkis, metadata semantik (seperti schema.org), dan navigasi intuitif yang memudahkan model bahasa meretrieve dan memahami konten secara akurat. Tanpa arsitektur ini, blog akan tertelan oleh volume informasi yang tidak terstruktur. Untuk mengevaluasi kesiapan, produsen konten harus bertanya: apakah infrastruktur blog kita sudah siap untuk menjadi sumber data primer bagi AI?
Indikator Kinerja Baru: Mengukur Kontribusi dalam Ekosistem AI
Metrik tradisional seperti bounce rate dan klik CPC menjadi tidak relevan. Sebagai gantinya, kita perlu mengukur retrieval rate (pangsa suara dalam hasil AI), engagement time pada snippet panjang, dan conversion dari user yang menggunakan informasi blog untuk menyelesaikan tugas. Visibilitas bukan lagi tujuan utama, melainkan posisi dalam 'peta pengetahuan' yang digunakan model generatif. Analisis data internal, bukan hanya Google Analytics standar, menjadi krusial untuk mengoptimalkan kontribusi blog.
Studi Kasus: Adaptasi yang Sukses dan yang Gagal
Banyak blog enterprise yang berhasil meningkatkan retrieval oleh model generatif setelah merancang ulang arsitektur informasinya. Mereka fokus pada struktur yang konsisten dan terukur. Sebaliknya, kasus yang gagal biasanya hanya mengandalkan optimasi SEO lama atau mengabaikan struktur data. Kesamaan keberhasilan adalah investasi pada kerangka kerja informasi yang konsisten dan terukur, membuktikan bahwa adaptasi arsitektur sangat penting.
Langkah Praktis: Membangun Infrastruktur untuk Retrieval
Untuk membangun infrastruktur yang siap untuk retrieval, lakukan checklist teknis: audit struktur URL, implementasi skema metadata, dan penyederhanaan navigasi untuk crawling efisien. Transformasi ini bukan proyek IT tunggal, melainkan kolaborasi lintas fungsi (redaksi, engineering, data). Gunakan alat-alat otomasi untuk memonitor performa sebagai sumber data bagi model pencarian generatif, sehingga konten kita selalu relevan dan mudah diakses.
Penutup: Kesimpulan dan Panggilan Aksi
Kesimpulannya, blog yang bertahan di era pencarian generatif adalah mereka yang menjawab pertanyaan: 'Bagaimana cara blog saya menjadi database pengetahuan yang berguna bagi mesin?' Adaptasi ini membutuhkan komitmen jangka panjang dan budaya iterasi berbasis data. Mulailah dengan mengidentifikasi entitas utama dalam niche Anda, lalu rancang arsitektur informasinya. Dengan demikian, blog akan tetap relevan dan memberikan nilai tambah di tengah perkembangan teknologi AI.